What this workflow creates
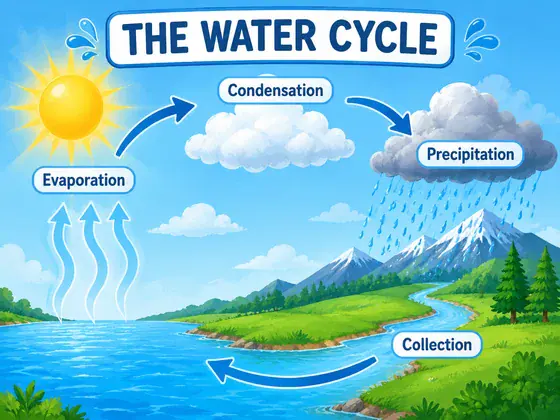
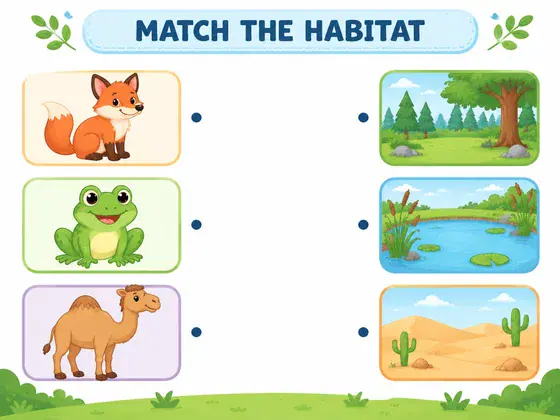
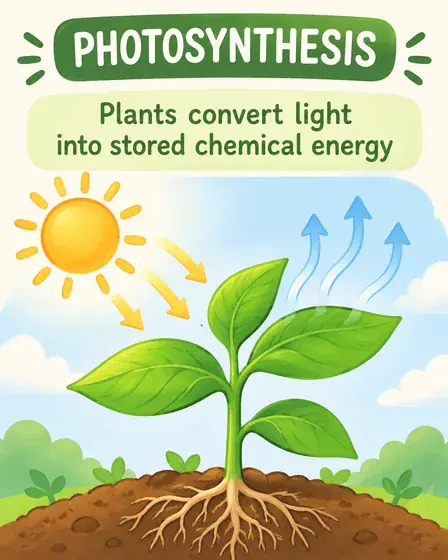
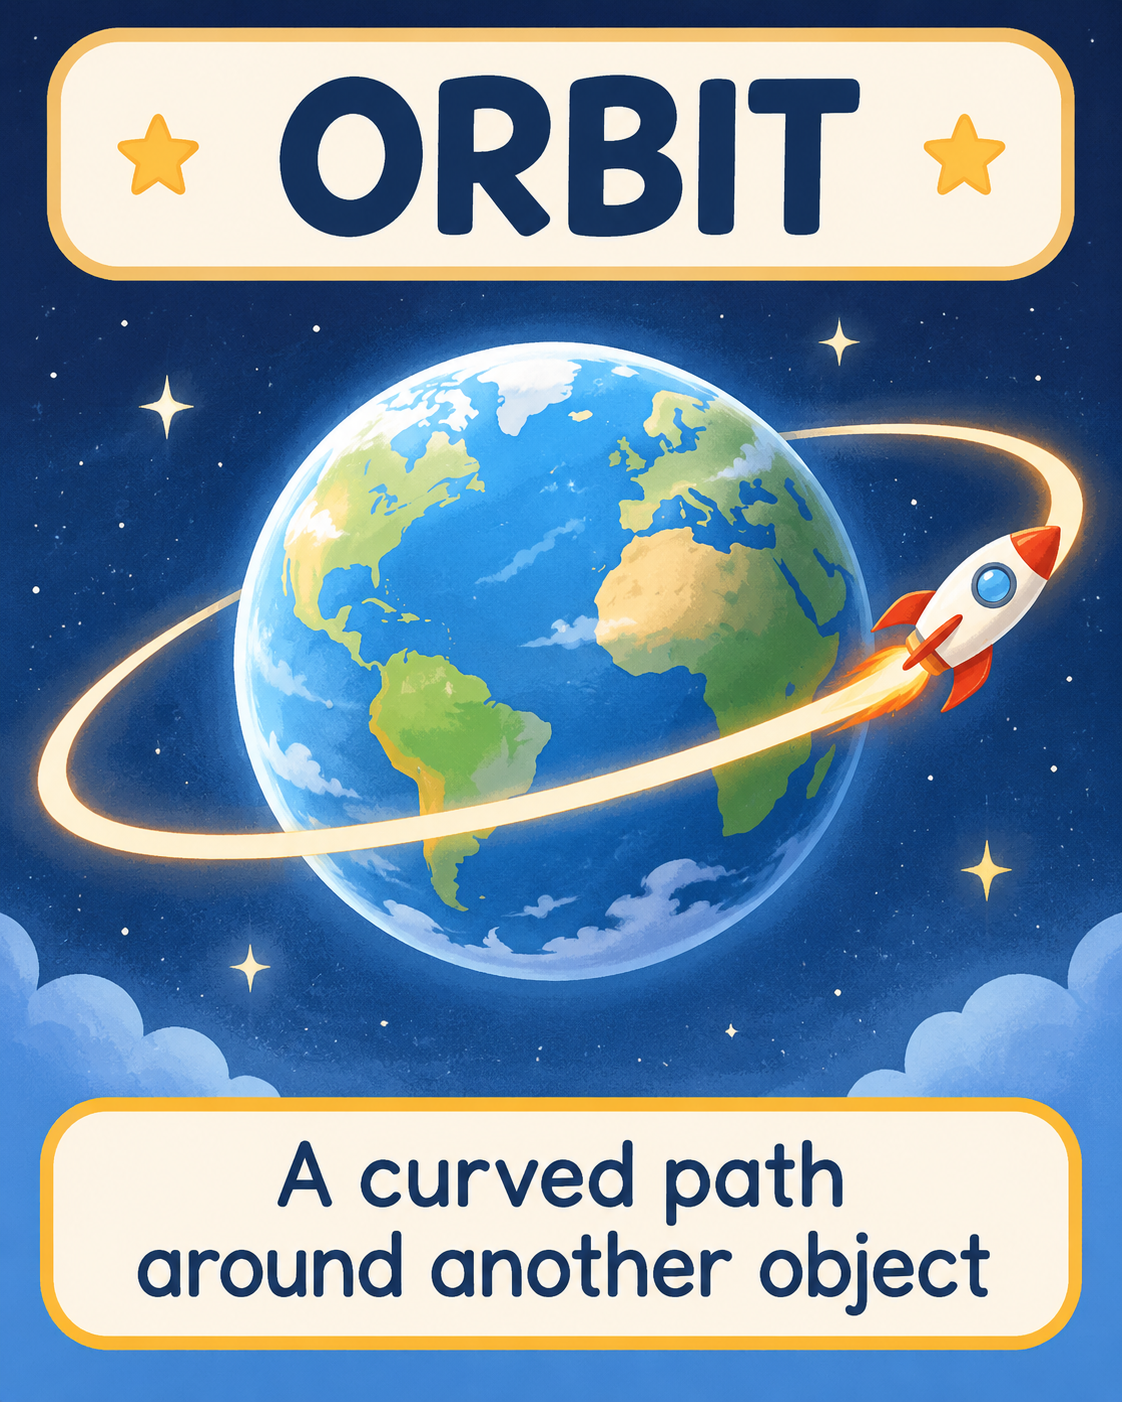
Generate vocabulary cards and contextual learning images. One image per request.
- Who it’s for
- language teacher, learner
- What it does
- Generate corresponding object or situation diagram
- Where to use it
- Classroom, learning applications
One image per request.
What you need
- This learning diagram typeRequired · 1 item
- Select the current delivery in the vocabulary card or situational learning map.
- Vocabulary, Definitions and Language FieldsRequired · 1 item
- Provide accurate vocabulary, parts of speech, definitions, target language and optional examples.
- learner stageRequired · 1 item
- Determine age appropriateness and semantic complexity of situations.
Provide every required input. Add optional inputs only when useful, and mark conditional inputs as applicable only when they apply to this request.
How to use this workflow
Open the generation form
Select “Use this workflow” to see the required inputs. You’ll need to sign in before generating.
Add the required inputs
Prepare: Required learning-visual type (1) + required vocabulary, definitions, and language fields (one set) + required learner level (1). Complete every required field, add optional inputs only when useful, and mark each conditional input as applicable or not applicable.
Review text and output settings
Check “This learning diagram type” and “learner stage” for accuracy, then choose the aspect ratio, resolution, and quality that fit this use case. The generation form shows the available options.
Generate and review
Select “Generate image,” then review the result and open the full-size image. Check it against the detailed requirements below. One image per request.
Do I need to write a prompt?
No full prompt needed—just complete the required text fields.
Complete “This learning diagram type” and “learner stage” to describe what this request should contain or create. “Vocabulary, Definitions and Language Fields” can be entered as exact text or data, or supplied as images. The checklist below shows which fields are required. You do not need to write generation instructions. Use the form fields to provide the images, exact copy, data, or description requested by this workflow.
Detailed result requirements
Required learning-visual type (1) + required vocabulary, definitions, and language fields (one set) + required learner level (1)
Subject, learner age/level, vocabulary/concept inventory, themes, color palettes, fonts and icons.
Each card focuses on a core concept; associated images and color coding provide visual clues.
Set the output canvas from the selected platform placement or production template, not from a reference image. Choose the option that matches this request: language-learning card working canvas — 4:5 (recommended). Use a different ratio only when a verified placement or production template requires it. If the platform does not require a fixed aspect ratio, use 4:5 as the recommended working canvas for language-learning card. Compose the subject with appropriate breathing room. Create one aspect-ratio-specific deliverable per request; generate each additional placement as a separate output. Recompose for the selected ratio while preserving the complete subject, all text, and every required safe area. Never stretch the subject or treat cropping important content as adaptation.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
No universal public standard is available. Check the requirements of the platform or service you will use.
Official and platform requirements
Unified printing size or ratio has not been found, it needs to be determined according to the final printing/digital platform.
FAQ
What can I create with this workflow?
Generate vocabulary cards and contextual learning images. One image per request.
Do I need to write a prompt?
Complete “This learning diagram type” and “learner stage” to describe what this request should contain or create. “Vocabulary, Definitions and Language Fields” can be entered as exact text or data, or supplied as images. The checklist below shows which fields are required. You do not need to write generation instructions. Use the form fields to provide the images, exact copy, data, or description requested by this workflow.
What do I need to upload?
No photo is required by itself. Provide the written or task materials listed on this page. Image-based materials may be supplied as JPG, PNG, or WebP files, up to 10 MB each. Export the required pages from PDFs, design files, or spreadsheets as images; exact text can be entered directly.
What does one generation produce?
One image per request.
Common search terms
Public evidence and sources
1 directly relevant public source has been found, and 4 types of specific constraints have been extracted. The following content only restates information that appears clearly from the source; no filling in of blank fields will be made.